
Ollama
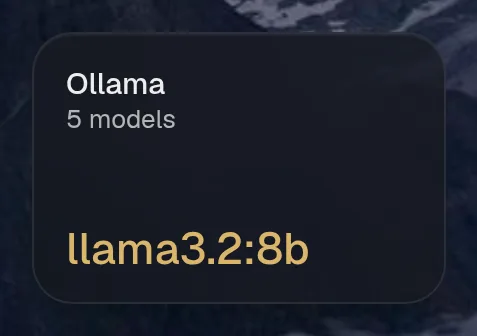
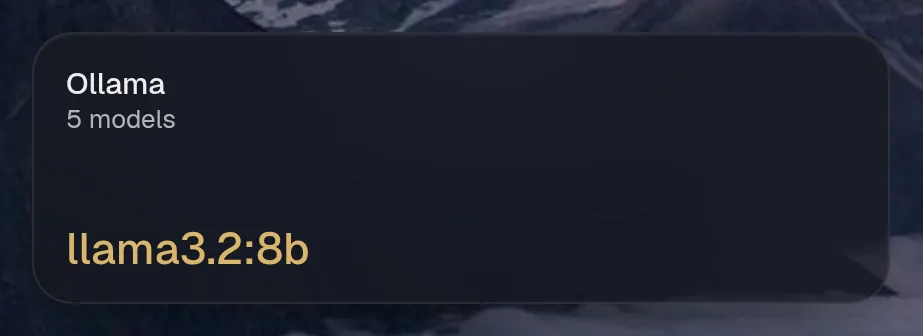
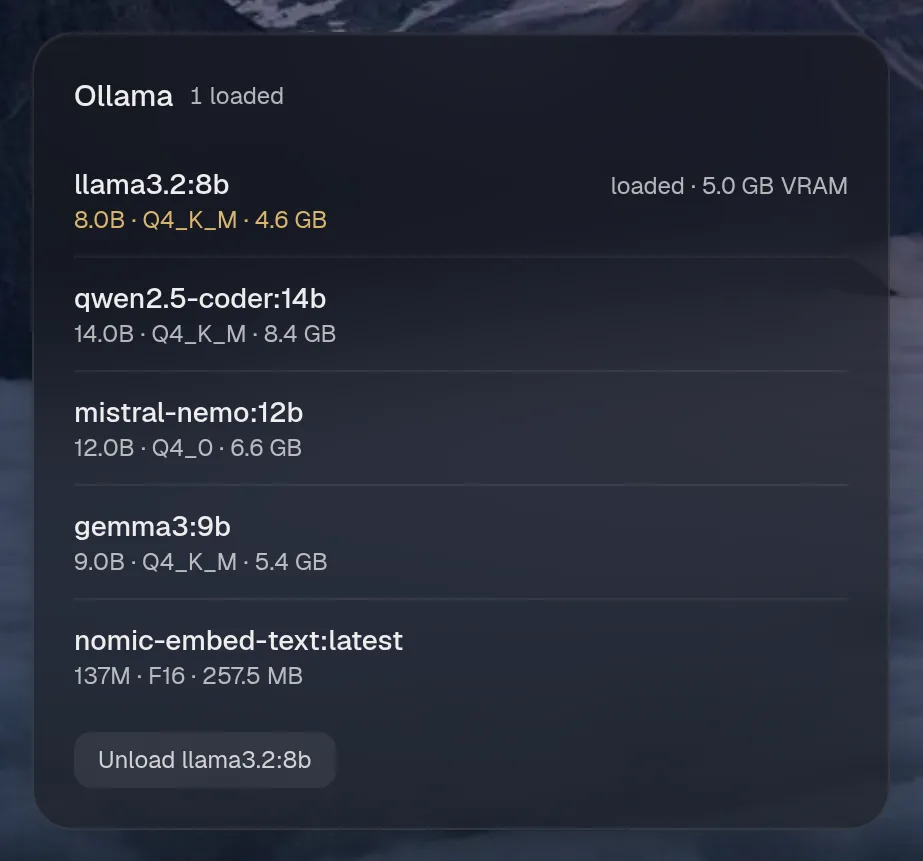
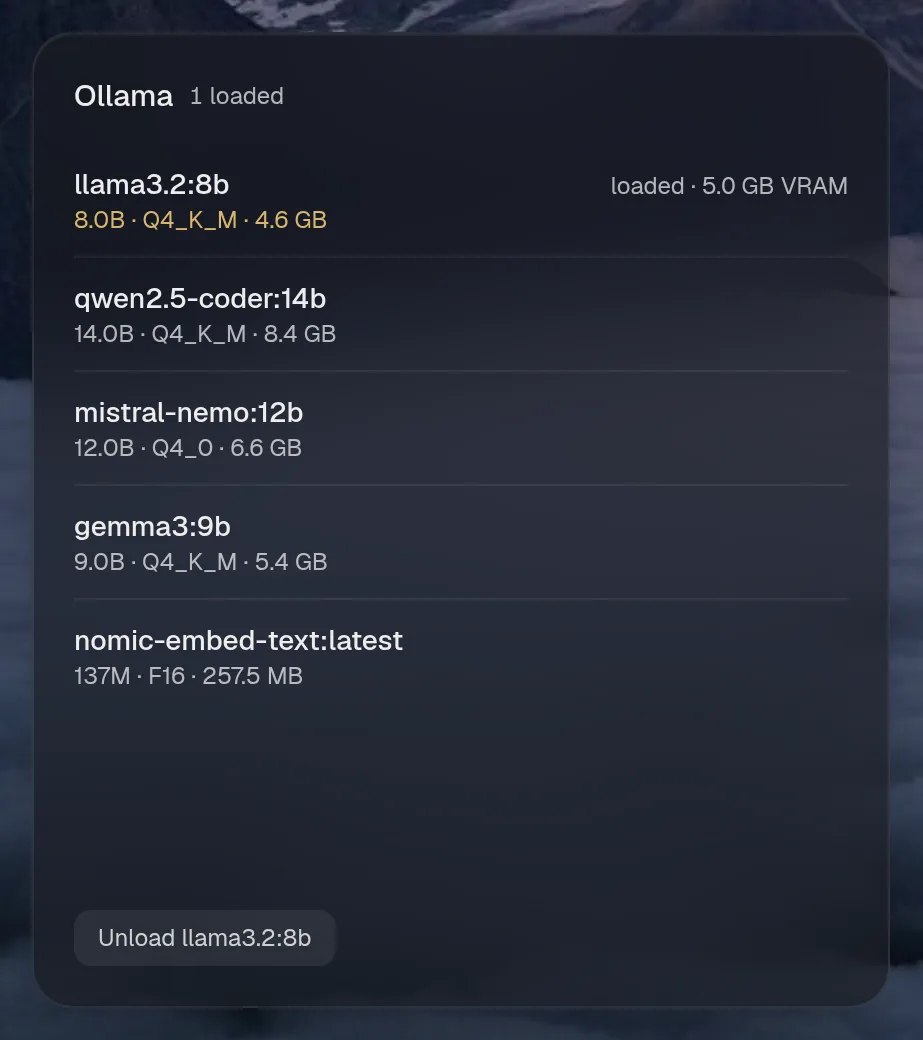
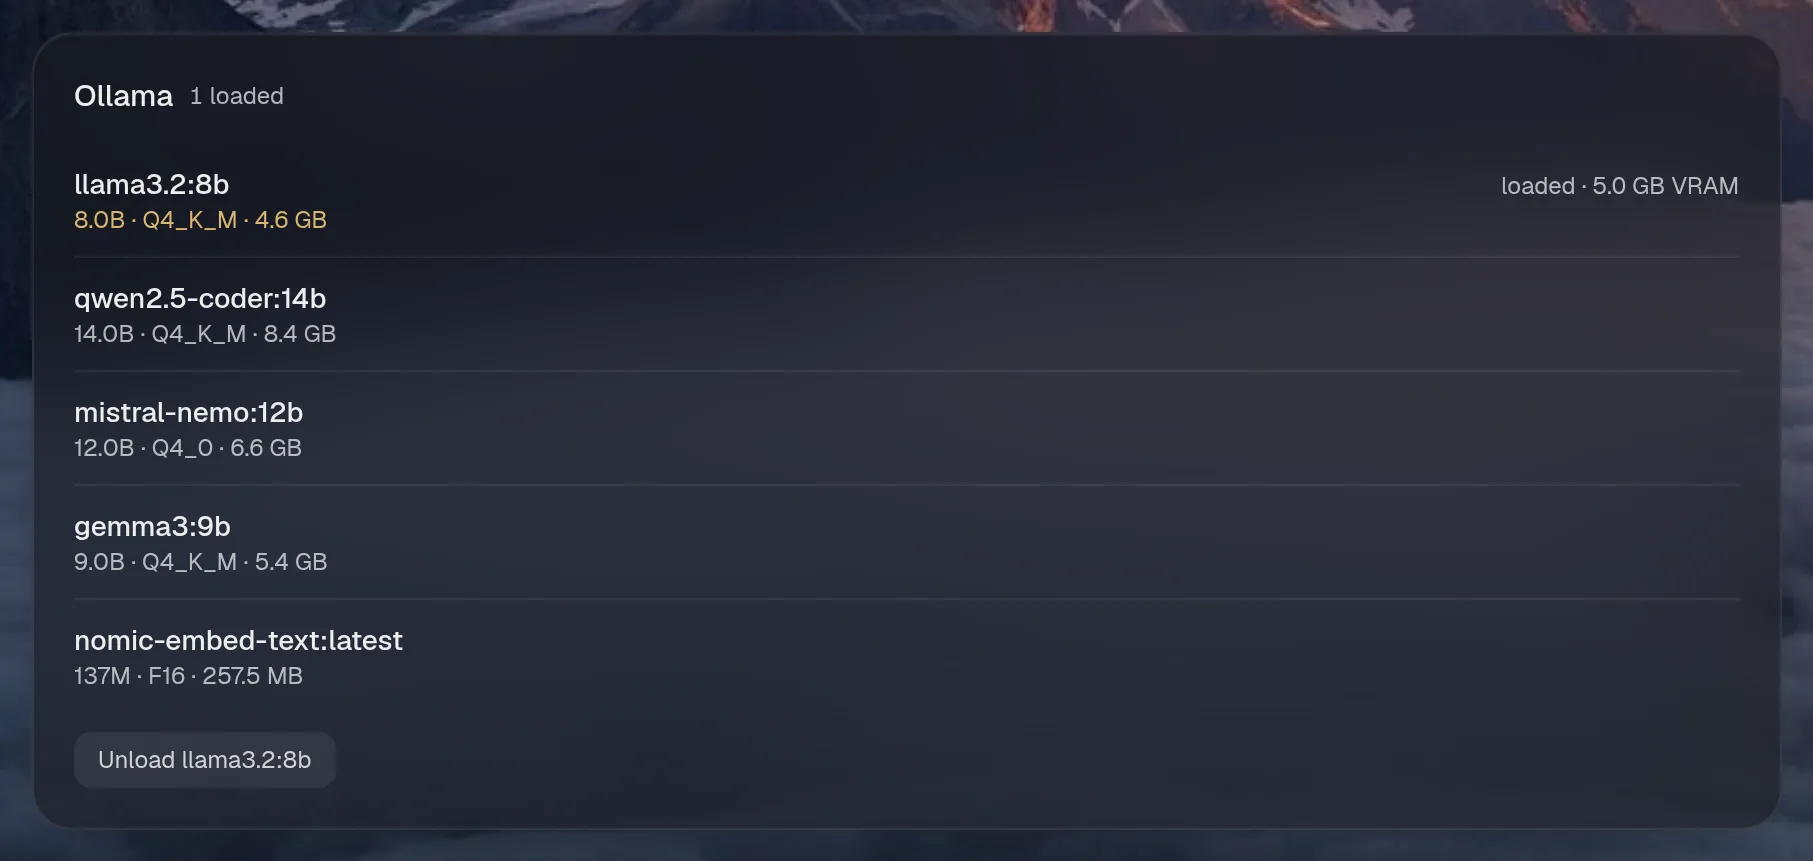
Ollama runs language models locally. This shows the models and which are loaded, and the assistant can unload one to free memory.
Set it up
Section titled “Set it up”integrations: ollama: type: ollama url: http://ollama:11434
layout: - title: Infrastructure widgets: - ollama.models| Option | Type | Default | What it does |
|---|---|---|---|
url | URL | required | Where the service answers, from Valet’s side. |
href | string | optional | Where the card links to, when that differs from url. |
Widgets
Section titled “Widgets”One widget. Its key is ollama.models, using the instance name from your config.
Ollama
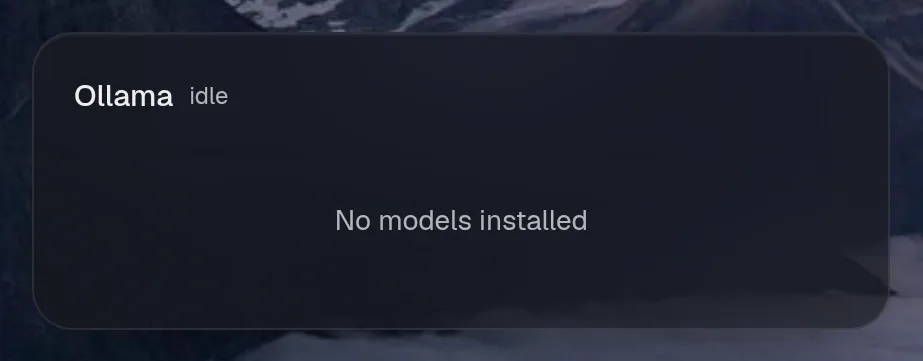
Section titled “Ollama”ollama.models · list card · refreshes every 30 seconds while the page is open.
States
Section titled “States”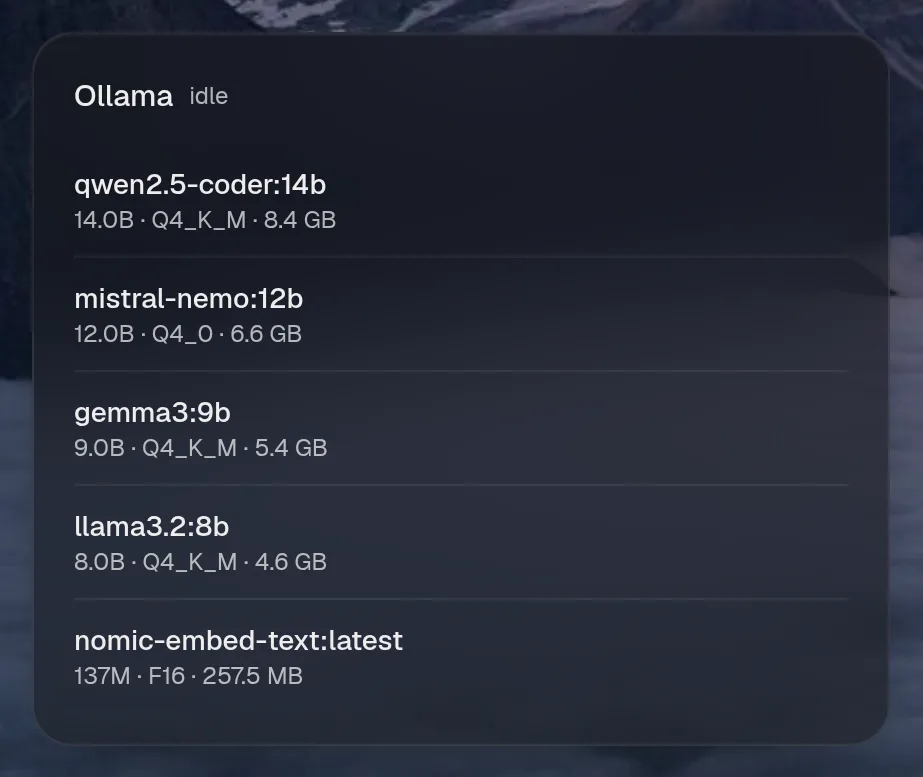
Assistant tools
Section titled “Assistant tools”What the assistant can use, once its access level allows it. Read tools run freely. Everything else asks first.
| Tool | Access | What it does |
|---|---|---|
ollama_unload | control | Unload a model from Ollama’s memory, freeing its VRAM. |
ollama_models | read | Models installed in Ollama, their size, and which are loaded in memory now. |
Actions
Section titled “Actions”What the page’s own buttons and controls can do. They need a signed-in person or a trusted network.
| Action | What it does |
|---|---|
unload | Unload a model from memory |